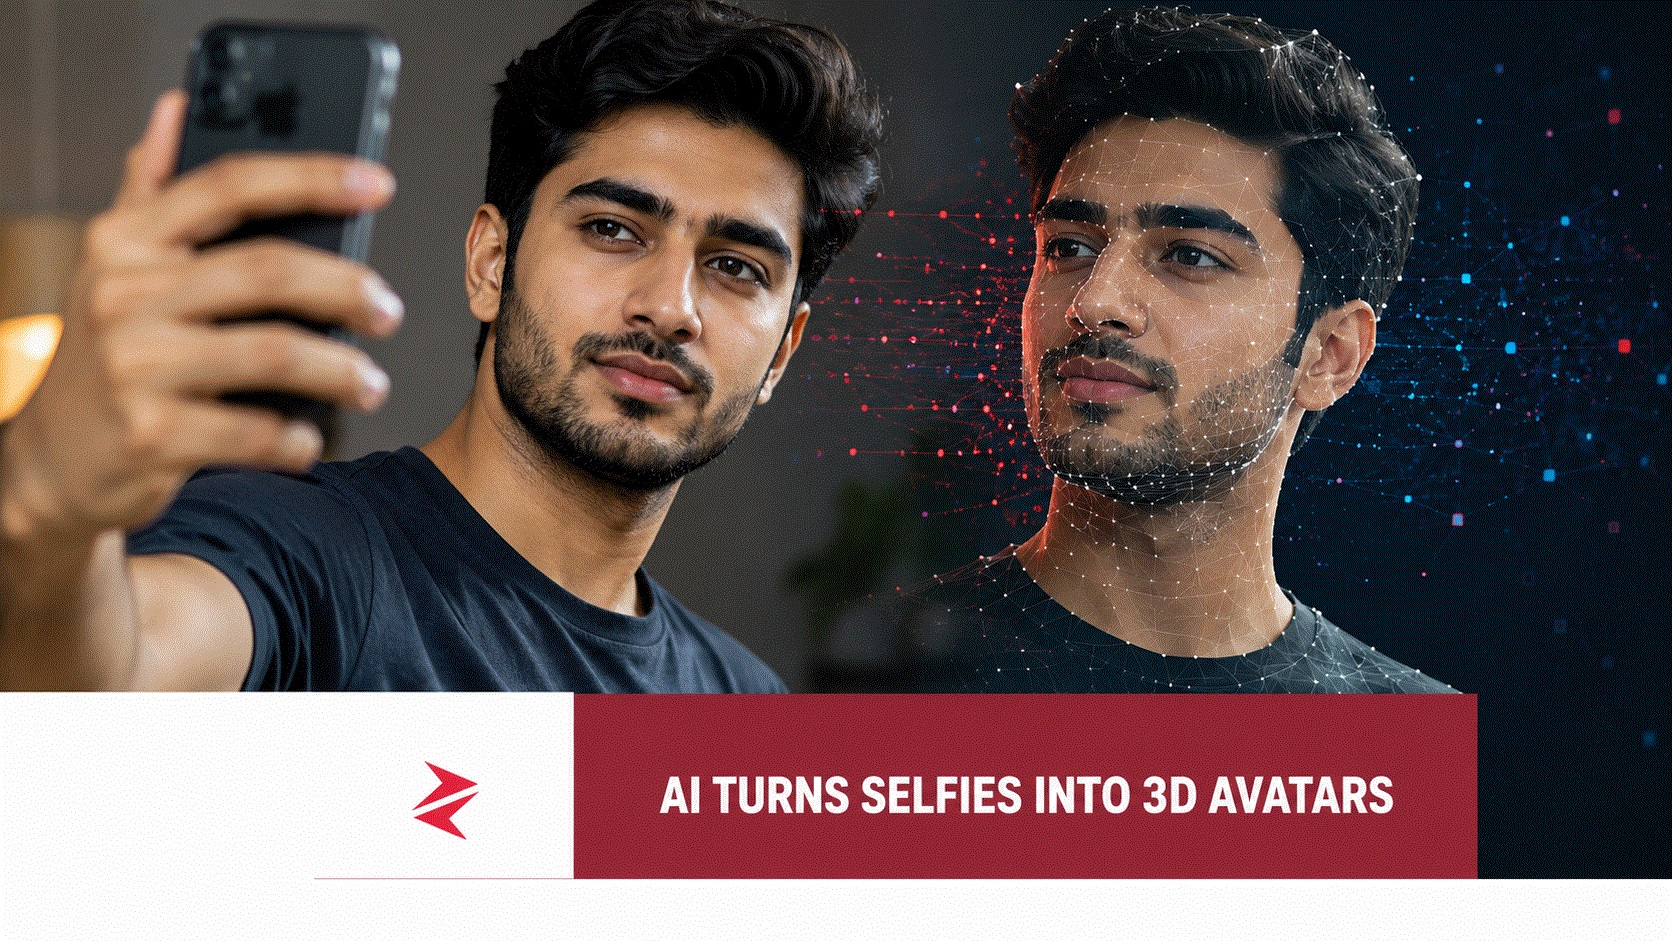
Artificial intelligence does not pull a hidden three-dimensional human being out of your selfie. It studies the visible evidence, estimates everything the camera failed to capture and constructs the most statistically plausible person behind the photograph.
That distinction destroys the most comfortable myth surrounding selfie-to-avatar technology. The machine is not discovering an invisible truth stored inside a JPEG; it is making a disciplined reconstruction from facial landmarks, lighting, perspective, learned human anatomy and millions of previously observed visual relationships. The result may look convincing enough to rotate, speak and enter a virtual world, but beneath the spectacle remains an engineered estimate—and a surprisingly important chapter of Pakistani technology history.
Years before generative avatars became a standard talking point across gaming, augmented reality and virtual production, a Pakistani team associated with Groopic and Ingrain.io introduced makeAvatar.ai, a service presented as a way to produce rigged and animated 3D avatars from selfie videos. Its surviving Product Hunt listing describes makeAvatar.ai simply as “AI to create 3D avatars from Selfies.”
The launch was small. The underlying ambition was not.
The Pakistani Startup That Saw the Avatar Economy Coming
Groopic had already attracted attention for using computational photography to solve an ordinary but stubborn problem: getting the photographer into a group photograph. The company’s next public experiment pushed beyond rearranging pixels and into reconstructing a person as a usable digital object.
According to the original launch description, makeAvatar.ai combined machine vision and artificial intelligence to turn a short selfie video into a rigged, animated avatar suitable for three-dimensional games, virtual reality and augmented reality. Ali Rehan, identified with the project and later associated with Ingrain.io, explained that the team encountered the difficulty of creating avatars while working on an internal project and decided to turn that difficulty into a product.
What nobody was telling Pakistan at the time was that this was not merely another amusing selfie filter. A rigged avatar is a reusable digital asset. It contains an underlying skeleton or control structure that allows the model to move, pose and animate. If that asset can be generated cheaply through an API, a developer no longer needs to employ a 3D artist for every individual user entering a game, virtual classroom, online store or mixed-reality application.
That is where the commercial power existed.
| Layer | What the system estimates or produces | Why it matters |
|---|---|---|
| Face detection | Position of the face, eyes, nose, mouth and other landmarks | Establishes the basic coordinate system |
| Pose estimation | Direction and rotation of the head | Separates facial structure from camera angle |
| Depth inference | Which facial surfaces are nearer or farther away | Converts flat relationships into estimated geometry |
| Hidden-surface completion | Likely shape of unseen cheeks, ears, jaw and rear of the head | Makes rotation beyond the original camera view possible |
| Texture generation | Skin colour, facial hair and other visible appearance details | Gives the geometry a recognisable identity |
| Rigging | Movable controls or an underlying skeleton | Allows animation and expression |
| Export or API delivery | A model usable by another program | Turns an experiment into infrastructure |
Factual note: These stages describe the general reconstruction pipeline. Individual products can combine, replace or omit stages depending on whether they generate a face, complete head, body, stylised character or photorealistic digital human.
A Selfie Is Not a 3D Scan
A normal selfie records colour and brightness across a two-dimensional grid. It does not directly record the exact depth of the nose, the shape behind the ears or the rear of the skull. Once the three-dimensional world has been projected onto one flat image, some information has been lost.
Artificial intelligence compensates by treating the photograph as evidence.
A system can examine how one cheek appears larger than the other, whether one ear is partly hidden, how the nose interrupts the background, where shadows fall and how facial components ordinarily relate in three-dimensional space. It then compares those clues with patterns learned during training.
The central claim is therefore straightforward:
A selfie-based 3D avatar is an inferred reconstruction, not a perfect extraction of the person photographed.
Research has established that detailed facial surfaces can be reconstructed from individual photographs, although pose, illumination, occlusion and missing views remain difficult. A foundational CVPR paper demonstrated an end-to-end neural network for detailed 3D face reconstruction from a single image, while later work such as AvatarMe pursued render-ready facial reconstruction from uncontrolled photographs. More recent research, including FaceLift at ICCV 2025, continues pushing single-image reconstruction towards higher-quality, full-head results.
The technology has improved enormously. The underlying uncertainty has not disappeared.
How AI Finds Depth Where the Photograph Contains None
Depth begins with relationships rather than isolated pixels. One pixel cannot explain a face, but thousands arranged around an eye, jaw or nose contain patterns from which shape can be inferred.
Occlusion provides one of the strongest clues. When the nose hides part of a cheek, or hair covers the forehead, the machine learns that the concealed structure probably continues behind the obstruction. Humans perform this completion unconsciously; a machine must learn it through data and optimisation.
Lighting provides another clue, but it can also deceive. A highlight may indicate a raised surface, while a shadow may reveal curvature. Yet dramatic lighting, makeup, compression artifacts and phone-camera processing can cause the algorithm to confuse illumination with geometry.
Facial landmarks then give the model a more stable map. Google’s current MediaPipe Face Landmarker identifies facial landmarks and expressions in images or video and explicitly lists virtual-avatar creation among its possible applications. A reconstruction system can use comparable landmark information to estimate pose, expression and facial proportions before generating a mesh.
| Visual clue | Likely inference | Common source of error |
|---|---|---|
| One eye appears smaller | That side of the face may be farther from the camera | Lens distortion or facial asymmetry |
| One ear is partly hidden | The head is probably rotated | Hair, clothing or cropping |
| Shadow beside the nose | Nose direction and projection | Uneven or coloured lighting |
| Jaw disappears behind a hand | The jaw continues behind the obstruction | Incorrect completion of hidden geometry |
| Forehead highlight | Possible surface curvature | Oily skin, flash or image enhancement |
| Moving expressions in video | Separation of identity from expression | Motion blur and inconsistent tracking |
A short selfie video can offer more evidence than a single photograph because it exposes the face from several moments or angles. Even then, the software must reconcile movement, expression and lighting into one coherent identity.